Network & Infrastructure
Zero trust in railway OT: What worked, what broke

Tõnu Tammer
Estonian Railways
Moving from an on-premises stack to cloud environments changes more than where applications run; it changes how traffic must be controlled throughout the transition. In this session, Uber and Cloudflare share how they are modernizing load balancing to route traffic safely between on-premises and cloud environments. Learn how Cloudflare’s flexible traffic controls and custom rules help Uber direct selected traffic to canary environments, validate changes, and expand deployments gradually. We also explore how Uber can rapidly shift traffic between environments as conditions change, reducing operational risk while allowing services to migrate on their own timelines.
0:03Thank you all for coming to our breakout session, Canary to Cloud, building a flexible traffic strategy. By way of introduction, my name is Noah Crouch. I am a senior public, senior product manager at Cloudflare, primarily working on our load balancing product, but also a few other things here and there. I'm joined today by Oscar Moreno Garza, who is a staff software engineer at Uber, working on the internet traffic team. I think I got that one right, internet traffic. As you may have noticed from the title track, today we are here to talk to you a little bit about traffic management. I'm going to walk through a little bit about what we're seeing in the industry today, where what we can call rudimentary traffic steering algorithms may break down, and how a robust system can overcome some of the challenges that arise in hybrid-type environments.
0:51Then I'll hand it over to Oscar, and he will go through how... uber scaled to over a million requests per second or about a million requests per second on the cloudflare platform encountered said challenges that i will have described and then how they solved those and led to a great success story so to get started let's kick it off with a statistic because everybody loves a good stat 73 that is the number of estimated organizations that are running a hybrid cloud set up today Hybrid cloud is a great buzzword, but what does it actually mean? It's not very descriptive. So included in this number, 73 % are organizations that are running any combination of multi -cloud, on-prem, or private cloud.
1:39So organizations that are running in AWS, Azure, GCP, included in this number. But more importantly, the type of organization that we're going to talk about today is the customer who may be running in GCP, but then also has... as compute and applications running in a private data center on -prem as well. So this number, 73%, has stayed mostly stable for the past five years. So why do customers and organizations run in a hybrid cloud environment? There are a variety of reasons. I spent a whole talk just going through those reasons, but ultimately it boils down to two reasons in particular. It's the fact that running on a hybrid cloud environment gives you unparalleled flexibility and resiliency cloud one has an issue if you're only in that cloud you're kind of out of luck you're down until they get back up which is not great for you not great for your customers multi-cloud environment hybrid cloud environment take the traffic that goes to that one shift it to the other and then you're good to go or god forbid both of those cloud environments are having a bad day the internet's just not happy today you can take some of that traffic shifted over as you on-prem environment and you're still somewhat up and running, giving your customers a better experience than they would have otherwise.
2:51So operating in the hybrid environment gives businesses an immense amount of agility, but it also introduces some very fundamental infrastructure challenges that make intelligent traffic management very critical and increasingly critical as we see more and more businesses adopt this type of operating. So let's take a look at some of those challenges. Challenge one is going to be heterogeneous hardware and environment. environments. So your backends are running in different environments. They are necessarily going to have different amounts of capacity. It's true even when you're running in separate clouds, it's going to be different behavior. Not every cloud is going to operate exactly the same. But more specifically, this is going to be especially true for the organization that has applications running in on -prem as well. I can absolutely promise you that the server that you have running in the dusty broom closet is going to have infinitely less scalability in compute than the application.
3:44that's running in the cloud environment. Second is the active-active type setups are becoming increasingly minimal and mandatory. In years past, you may have run active-passive, let's send all of my traffic to one data center, wait for a disaster to hit, we'll be down for a few minutes, route traffic over to the other data center. Over with active-active, typically find that organizations have better resiliency and global performance overall. It's much easier to route traffic to a new data center that's already accepting traffic as opposed to trying to spin one up do a dr and send traffic to a cold site then third challenge failures can cascade very very quickly so if environments have differing amounts of capacity there's a very real risk of a thundering herd type problem that leads to cascading failures so we'll go back to the example we gave a little bit earlier imagine you have an application running in the cloud some of those nodes go down become unhealthy. We'll take that traffic, shift it elsewhere.
4:40Except we've just shifted so much traffic into our on -prem environment and how our on -prem environment is also unhealthy. So now we have to take all of the traffic that was going to our on-prem environment, shift that back to the cloud, except that cloud is busy tearing down unhealthy nodes and spinning up new nodes. So then you just have a thundering herd, unhealthy, unhealthy, unhealthy, unhealthy, so on and so forth. Again, not great for anybody. So when teams attempt to solve these challenges and bridge these hybrid environments, which are called rudimentary or typical traffic management techniques, the architecture inevitably fractures against and across a variety of failure modes. We're going to focus on three particular failure modes today.
5:26First one is under or over -utilization because of blind round -robin traffic steering. That is a mouthful. Uh, round-robin is the... simplest the steering algorithm that you're going to find out there let's take request one send it node one quest two send it node two so on and so forth uh it's still around because it's incredibly effective except it's incredibly effective in very specific circumstances those circumstances being you're operating in an environment where all of your different environments have homogenous amount of capacity we're literally just taking the load shifting it out as evenly as possible about all of our different centers. But this begins to break down in heterogeneous environments with differing amounts of capacity, in which case you're either going to under -provision and your lower capacity sites are going to become overloaded, shift traffic elsewhere, or you're going to over-provision and then you're just going to be wasting money because you've over-provisioned and you're doing blind round -robin.
6:23So then surely a potential solution here is that we want to maybe route by latency. Yeah, it's got to be the solution. Unfortunately, again, probably not. Latency-based steering can work great, or it's great in homogenous environments, can also work great in some multi-cloud environments, because the latency that you're going to find from the end user to any of the big public clouds is typically going to be somewhere around the same. But as soon as you introduce on-prem hardware into the equation, the math just completely changes. So you have your cloud -based application will attract all of the traffic because it's going to be responding the most. quickly unless your users are directly co-located which typically is not going to be the case and then you have two outcomes outcome one your on-prem is just never going to see any traffic whatsoever you're going to be wasting money because you have servers that are sitting idle or outcome two you have issues in the cloud you try to shift traffic onto the on -prem and then we have that same thundering curve problem that we talked about earlier the third failure mode is configuration sprawl so say you want to do something as simple as manage a canary environment ordinarily that's going to be as simple as configure a few routing rules you know query query string header configure those routing rules boom you've got a canary environment when you're doing hybrid environments you then have to take that configuration replicate it from one spot to the next spot still not great even though there's maybe different configurations but what happens when you scale that to 10 applications and
7:54then 50 applications 100 applications applications as we'll see here in a little bit uh the management simply becomes untenable yeah there's ways to automate it but they're not they're not good solutions so to prevent these failures we have to move past and blunt routing rules and adopt a more intelligent capacity aware traffic management strategy uh a intelligent traffic management strategy should be able to accomplish at least these things probably more so capacity -aware distribution instead of doing something like proximity steering, blind round robin. You need to be able to direct your traffic on something more closely resembling the actual capacity of your backends. You need to be able to have programmable and easily manageable edge rules to take care of those edge cases, the canary use cases, things like that.
8:42Importantly, you need to be easily manageable. And then finally, you need uninterrupted resilience. We mentioned earlier that active-active is becoming the norm for both performance and cost reasons. An intelligent traffic... management platform needs to be able to failover seamlessly in near real time and take traffic that was destined for one location and shift it in a capacity aware manner to other locations now up until now this may have sounded all boringly theoretical i promise you it's not this is the exact production architecture that uber has deployed to scale on their cloudflare platform from zero request as of 2023 up to over a million requests per second today so i will invite oscar up on the stage as he's making his way up here we'll take a quick brief look at the time frame of uber's on ramping welcome oscar starts in 2023 we've got onboarding fast forward six months we are live in production six months later we're doing active active with cloudflare feature parity is at 99 and 30 of traffic's on cloudflare fast forward a little bit before today we're at 50 of core trips 100 of critical web app That's 100% of employee traffic.
9:51So with that, I'll hand it to Oscar to talk through the problems they encountered in this journey and how they solved them.
10:02Yeah, so my name is Oscar Marino Garza. I'm a software engineer on the internet traffic team, which, you know, you can probably guess from the name we handle the internet traffic coming into Uber. Just going to talk about some of the problems we've run into as we scale the systems. I think, like, you know, organizations are going to run into these problems sooner or later as you scale your systems. I also want to call out, like, these particular solutions make a ton of sense for Uber, but they might not be the best fit for your organization. So, you know, your mileage may vary. So, yeah, these are not silver bullets. Okay, yeah. So, big picture, right? H-2023. Uber started. with a single cloud provider, which was the FastPath.
10:49And then we had on -prem data centers that we could use as a backup. Fast forward to 2026, we now have ActiveActive with both GCP and Cloudflare as the FastPaths. But also, we retained the data center on -prem capacity, but we honestly don't use it that much. Now, this doesn't mean like, oh, it took us like three years to... onboarding to Cloudflare. No, it actually took us like around six months to serve like a decent amount of traffic. But we are continuing to work with Cloudflare on multiple different things. You know, HTTP3, the standardization is one thing that comes to mind. So there's like an ongoing effort going on. Yeah, and then just to clarify, like that MVP, six months, rider traffic.
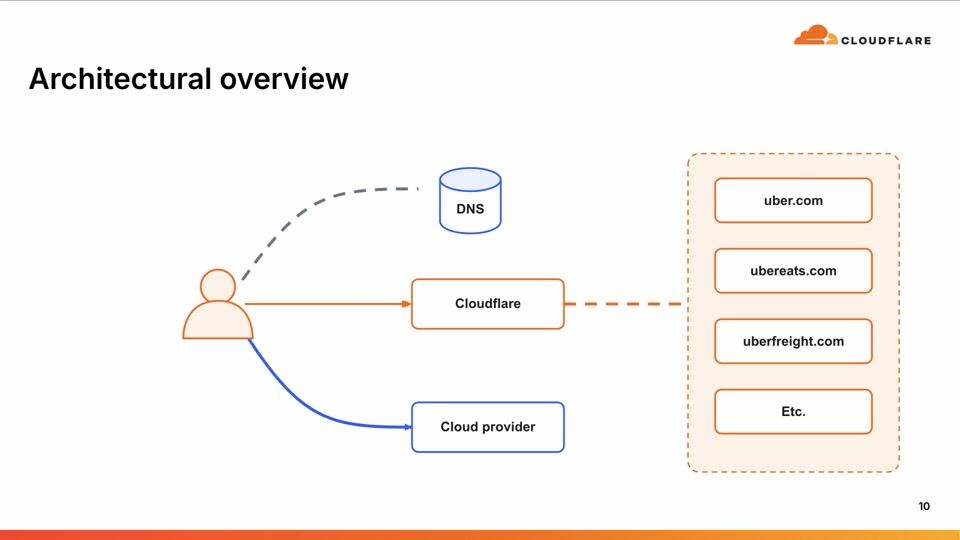
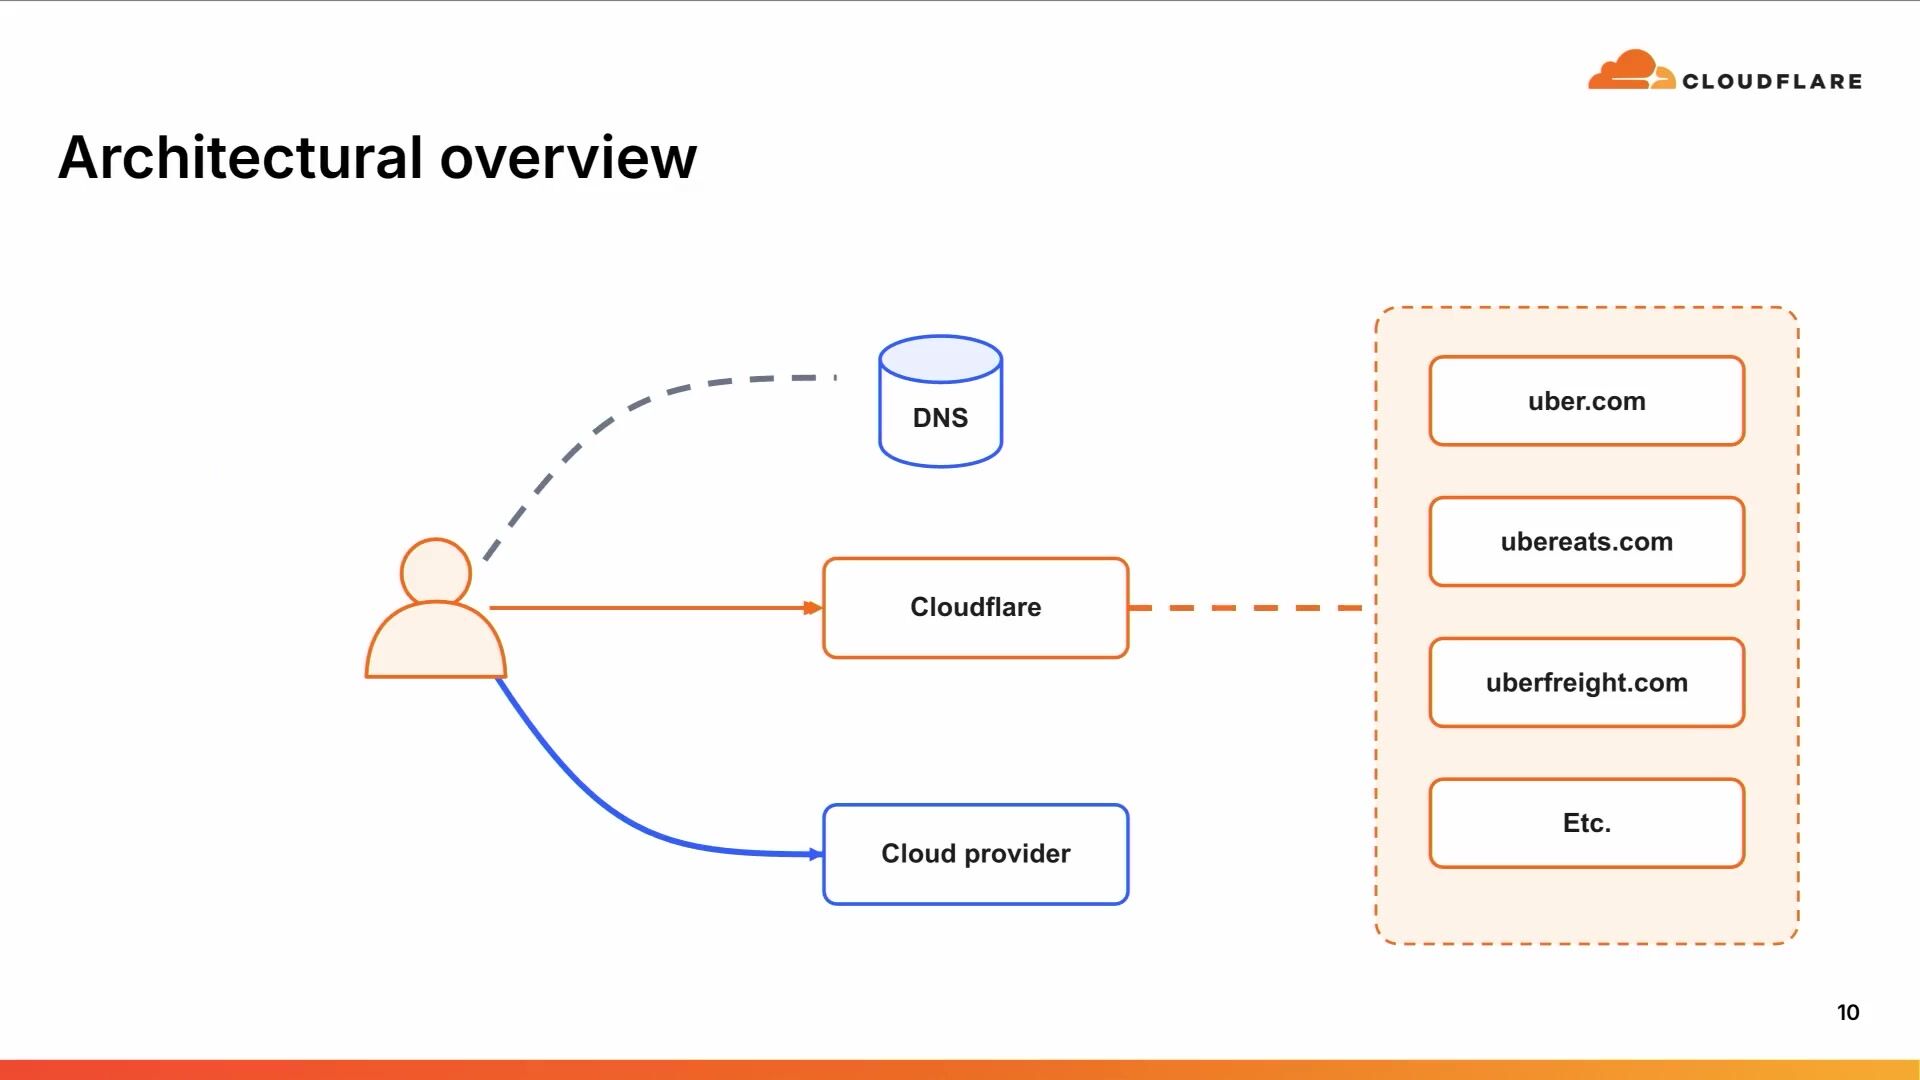
11:37So if you ever requested an Uber, Uber Eats. That sort of stuff. Yeah, so basically, at the core, we have DNS that handles the kind of like, we have like a weighted DNS setup for ActiveActive, which we will send you to Cloudflare or GCP in this case. But for this, we're going to like focus on the Cloudflare configuration, which is pretty straightforward. We basically have a single zone for each. top -level domain. So, one for Uber .com, Uber Eats, so on and so forth. Right now, we have around like 120 to 115, I want to say. They keep growing. Yeah, but in general, for each particular website we have, we actually have around 6 ,000 configurations.
12:26So, overall, across all of those aggregated, 6 ,000 different website configurations. And what do I mean by configuration? It's like term right so basically like nginx and our proxy configurations later down the stream so where do i route to uh on the uber service match what else what is like the authentication level for this request and then there's also like things like okay what kind of parameters does this map against our ddos efforts so a lot of those it's a pretty big configuration there's 6 000 of them um it's It's a lot to manage. So obviously we don't want to create 6,000 Cloudflare configurations for this.
13:12That's why we only create the top zones and then manage the more like Uber specific logic inside our Amboy proxy and NGINX services. I also want to say like, in general we are currently handling right now around like 2.2 million requests per second. So half of that traffic goes to Cloudflare, but also during important dates such as Halloween, 4th of July, that traffic can add doubles, right? So we have to also keep that in mind when we are designing our systems.
13:50Now, this doesn't mean like, okay, you mentioned there's a lot of over-specific logic later down the stack. This does not mean like Cloudflare is just like a simple proxy. We just send all of... the traffic. No, no, it handles like a lot of really important configurations and like most notably like TLS, MTLS for some users, DDoS, volumetric protection, but also the first hope in our load balancing scheme. Right. So I'm going to talk a little bit about the Uber kind of like architecture. At its core, we have like a regional topology and we have two. regions, DCA and Phoenix, and they are named after the closest data center. So there's one in Washington, one in, you know, closer to Arizona. And then inside those regions, we have zones.
14:42And, you know, for the example, for Phoenix, we have like Phoenix 7, 8, and 9. These are kind of like what we look like a couple of months ago, where all of those zones are on -prem. So they look pretty much the same. Even though if you've read like blogs about Uber, our compute kind of like closer is heterogeneous. We are kind of like a special team. We get like special preferential treatment. And all of our hardware looks the same to help us make sure that we're able to route traffic safely to the backend services. So for this particular configuration, everything looks the same.
15:22Yes. Yeah, I also want to say like.
15:28The way that this is designed as it is, is because whenever there is like an issue on a region or a particular zone, we are able to quickly just flip a switch and enable or disable one of the pools or the backends, the endpoints, and it just takes like a couple of seconds, which is amazing. I don't know what kind of Magic Cloudflare is running there, but it's so good to know that you can drain in like one or two seconds.
15:57Now, here's kind of like the first problem, is what happens when your assumptions around homogeneous capacity but also latency are broken, right? So there's this big push to migrate to cloud and we set up a cloud zone. Everything's perfect, everything works, but the moment we start sending traffic to it, we realize, okay, there's two problems here. One is the new Cloudflare back zones have like a much better latency, right? Usually cloud providers are much better latency than if you go and build your own data center, right? They just have those intercontinental cables in the sea, right?
16:43But also the other problem is not only the latency is better, but the throughput for this new... servers is actually a lot better too, right? So now you have like those two problems that you have to figure out, right?
17:00So, yeah. I mean, if you just go and use one of like the default.balancing algorithms, like that might work out like perfectly okay, right? Specifically if you're like just focusing on latency because latency will encode things like capacity by default. But we care not only about latency, but also about the utilization, right? We want to make sure that if we are paying for a specific server, we actually get the full use out of it so we can pass the savings to the customer.
17:34So how do we become explicit and encode this sort of capacity slash latency on the backends? Yeah, so luckily for us, there is a very well -known algorithm that Cloudflare already has on the traffic stack. It's called weighted round robbing, and it's super simple. You just set a weight for each backend inside your pool, and then you can play around with the capacity and latency and a bunch of different factors. And then for our Phoenix 50, so on, which these are mostly real numbers, we just kind of put a... 2x factor on it. So that gets like 50 % of the internet traffic, and then the other legacy on -prem servers get 25 % and 25 % each.
18:20So now everything is like perfectly balanced, right?
18:29Yeah, I know like with it's round robin, it's probably not like super groundbreaking, but honestly, I kind of love it. I feel like you have to be like a genius to come up with this with the algorithm in itself. actually you can like encode so many different things and look into that particular number um so for us we care about the latency there's like some piece of code somewhere running on the uber stack that updates this on the flies based on capacity uh throughput and also like the latency um yeah i want to kind of like have a little pause here and give a bit more context about some of the uber architecture before we go into the second problem and basically the main thing you need to know is the mobile application actually uses like different hostnames, like DNS hostnames in order to run different sort of experiments, right?
19:26We mentioned like HTTP3, there's a specific hostname we are reserving to do some testing on HTTP3 We have this service called Dispatch Center which, you know, at its core I mean, it's a very complicated service core, it's a key value data store, and you can map a request to a specific host name and then map that particular host name to an experimental group, right? And then an experimental group has some routing, some Uber -specific routing characteristics that will push you to a specific instance on our Kubernetes cluster. So using this dispatch center service is how we've implemented Canary Routing for Uber. So, yeah, actually, I guess, like, surprise announcement also for Uber employees.
20:13We've been running this for a couple of months now. We've never made it kind of public. But if you're an Uber employee, you are already, like, being to Canary right now. If you open your mobile application and just look at the network logs, you will see, like, CN Canary, CN Canary. But, yeah, just a little bit more context. CN.uber.com is our main API. CN Canary is like our new Canary host name. So, okay, here's a bit more context. We have this system that kind of rolls out in a sequential manner to two different zones. And inside our stack, we reserve DCA 20, the zone specifically for Canary.
21:01So this is like a very small zone. supposed to serve at max 2% of the global traffic.
21:09So here's the problem. How do you make different routing decisions
21:15for different subdomains, right? So we have seen .uber.com, which is our main configuration. We are perfectly happy with it, right? But now we want to say, okay, for seeing cannergy.uber.com, we want to change the routing. Now we want to include the SA20 and maybe ISO. DCA20 so that all of the canary traffic is like isolated into that particular zone which all of the over services for canary are running in and it gets like scrutinized for like metrics and logs and observability um so yeah there's kind of like the naive solution and I mean I think I think this kind of works if if your scale is not like super big or you don't care to manage 6 ,000 zones and duplicating that but you can just say okay let's just make create a cloud first zone for cncana readover .com right we talked about earlier how we don't do that and that is because then our configuration will grow like exponentially and I mean we just don't manage that right like that's that's a nightmare to manage so if only there's like a way in which you know you can define an exception for a configuration without actually taking extra complexity in either one exploring your configuration or the other kind of thing that we thought about doing is, okay, we have this system that pushes configuration to Cloudflare.
22:42What if we add like a little if branch in there? If you are seeing canary.uber.com, then just create that particular zone and then do something else for the rest. Yeah, none of those. are particularly interesting for us. Like, they're not very something we want to manage at additional if branching or manage, like, a huge configuration set. So, yeah, turns out there is already a thing that we're leveraging, and I want to give a shout-out to Chris Martinelli because we can engage with him.
23:23trying to come to a solution to this problem. And, you know, the suggestion was, okay, just use the load balancer custom rules. And, I mean, yeah, I mean, I think this makes sense, right? If you're not familiar with the custom rules, they basically allow you to map a particular request to an action, right? And in the case of cncannery.rober.com, like, it might be unsurprising that we map that particular host name, and then we set up an override pull action, and we only have... DCA20 as a primary pool. We have the rest of them for backup in case DCA20 has an issue. But in normal operation, everything is isolated to that particular
24:04There's a couple of things that I really like about this approach. One is you don't have to create 6,000 zones, right? 6,000 clausular zones. That would be madness. And then the other one is even if you were to create the 6,000 zones, you have to think about okay, am I going to create, like, duplicate load balancers for each zone? Am I going to create, like, duplicate pools? Are the pools going to share health checks? Are they going to duplicate the health checks? Yeah, health checks alone are, like, a significant amount of traffic for us. So, actually, this solution just allows us to say, okay, we just have, like, one extra pool that we can share across all of the zones, just one extra health check that we are able to kind of, like, ramp up and be a little bit... more quick on that health check and failover faster.
24:50And then the other thing that I really like is that actually like if you look at the configuration in itself, it's the same across every zone, right? Yeah, I mean sure you have like that kind of like branch on the rules itself, but if you look at the configuration and what you need to understand as a human, everything is the same for all of the zones. So yeah, that's what we end up using. And I think that's it.
25:15Throw it back to you.
25:20Thank you.
25:23Oscar. So everything we heard Oscar talk about, think about the weighted round robin specifically. I want to give a quick preview of something that's going to be coming very soon to look out for their load balancing. It's called dynamic load shedding. You may hear this referred to in other contexts as feedback-based load balancing. With something like weighted round robin, it's still on you to intuit what the... of a particular area, particular application is. With feedback-based load balancing will allow you to return a load metric for a particular origin. This one's a 10%, 20%, 30%. That can be CPU, that can be an arbitrary metric, whatever it is that you decide. Do our active health checks. Then within Cloudflare, you set a target. And then once we begin to meet and exceed that target, we will actively shed traffic away from that endpoint and pool to prevent it from becoming overloaded in the first place.
26:11So rather than having to guess that, yeah, 30%, 50%, whatever, works. We're actually low-bounding based on the capacity that you're returning to us. Then a little bit later down the line, dynamic origin registration. We're exploring ways that we can integrate with the dynamic scaling nature of a lot of workloads today, so that rather than having to run API calls, we can just autonomously know that you're scaling up and down, add those new endpoints to pools, and then everyone's happy because you don't have to manage scripts. and things like that.
Tõnu Tammer
Estonian Railways
Doug Suttles, Lai Yi Ohlsen
Orb · Cloudflare
Steve Goldsmith, Mattie Toia
Cloudflare · Uber
Be the first to know when registration opens and the agenda goes live.
---
title: "Canary to cloud: Building a flexible traffic strategy"
url: "https://www.cloudflare.com/connect/2026/session/canary-to-cloud-building-a-flexible-traffic-strategy"
year: 2026
---

# Canary to cloud: Building a flexible traffic strategy

[Watch session](https://www.cloudflare.com/connect/2026/session/canary-to-cloud-building-a-flexible-traffic-strategy)

## Session details

- **Track:** Network & Infrastructure
- **Topics:** App modernization, Customer Experience, Hybrid cloud, Network modernization & multicloud, Performance & resiliency
- **Solution areas:** Application Performance

## About this session

Moving from an on-premises stack to cloud environments changes more than where applications run; it changes how traffic must be controlled throughout the transition. In this session, Uber and Cloudflare share how they are modernizing load balancing to route traffic safely between on-premises and cloud environments. Learn how Cloudflare’s flexible traffic controls and custom rules help Uber direct selected traffic to canary environments, validate changes, and expand deployments gradually. We also explore how Uber can rapidly shift traffic between environments as conditions change, reducing operational risk while allowing services to migrate on their own timelines.

## Speakers

- [Oscar Moreno Garza](https://www.cloudflare.com/connect/speakers/2490271) — Staff Software Engineer, Uber
- [Noah Crouch](https://www.cloudflare.com/connect/speakers/2490268) — Senior Product Manager, Cloudflare

## Transcript

[0:03] Thank you all for coming to our breakout session, Canary to Cloud, building a flexible traffic strategy. By way of introduction, my name is Noah Crouch. I am a senior public, senior product manager at Cloudflare, primarily working on our load balancing product, but also a few other things here and there. I'm joined today by Oscar Moreno Garza, who is a staff software engineer at Uber, working on the internet traffic team. I think I got that one right, internet traffic. As you may have noticed from the title track, today we are here to talk to you a little bit about traffic management. I'm going to walk through a little bit about what we're seeing in the industry today, where what we can call rudimentary traffic steering algorithms may break down, and how a robust system can overcome some of the challenges that arise in hybrid-type environments.

[0:51] Then I'll hand it over to Oscar, and he will go through how... uber scaled to over a million requests per second or about a million requests per second on the cloudflare platform encountered said challenges that i will have described and then how they solved those and led to a great success story so to get started let's kick it off with a statistic because everybody loves a good stat 73 that is the number of estimated organizations that are running a hybrid cloud set up today Hybrid cloud is a great buzzword, but what does it actually mean? It's not very descriptive. So included in this number, 73 % are organizations that are running any combination of multi -cloud, on-prem, or private cloud.

[1:39] So organizations that are running in AWS, Azure, GCP, included in this number. But more importantly, the type of organization that we're going to talk about today is the customer who may be running in GCP, but then also has... as compute and applications running in a private data center on -prem as well. So this number, 73%, has stayed mostly stable for the past five years. So why do customers and organizations run in a hybrid cloud environment? There are a variety of reasons. I spent a whole talk just going through those reasons, but ultimately it boils down to two reasons in particular. It's the fact that running on a hybrid cloud environment gives you unparalleled flexibility and resiliency cloud one has an issue if you're only in that cloud you're kind of out of luck you're down until they get back up which is not great for you not great for your customers multi-cloud environment hybrid cloud environment take the traffic that goes to that one shift it to the other and then you're good to go or god forbid both of those cloud environments are having a bad day the internet's just not happy today you can take some of that traffic shifted over as you on-prem environment and you're still somewhat up and running, giving your customers a better experience than they would have otherwise.

[2:51] So operating in the hybrid environment gives businesses an immense amount of agility, but it also introduces some very fundamental infrastructure challenges that make intelligent traffic management very critical and increasingly critical as we see more and more businesses adopt this type of operating. So let's take a look at some of those challenges. Challenge one is going to be heterogeneous hardware and environment. environments. So your backends are running in different environments. They are necessarily going to have different amounts of capacity. It's true even when you're running in separate clouds, it's going to be different behavior. Not every cloud is going to operate exactly the same. But more specifically, this is going to be especially true for the organization that has applications running in on -prem as well. I can absolutely promise you that the server that you have running in the dusty broom closet is going to have infinitely less scalability in compute than the application.

[3:44] that's running in the cloud environment. Second is the active-active type setups are becoming increasingly minimal and mandatory. In years past, you may have run active-passive, let's send all of my traffic to one data center, wait for a disaster to hit, we'll be down for a few minutes, route traffic over to the other data center. Over with active-active, typically find that organizations have better resiliency and global performance overall. It's much easier to route traffic to a new data center that's already accepting traffic as opposed to trying to spin one up do a dr and send traffic to a cold site then third challenge failures can cascade very very quickly so if environments have differing amounts of capacity there's a very real risk of a thundering herd type problem that leads to cascading failures so we'll go back to the example we gave a little bit earlier imagine you have an application running in the cloud some of those nodes go down become unhealthy. We'll take that traffic, shift it elsewhere.

[4:40] Except we've just shifted so much traffic into our on -prem environment and how our on -prem environment is also unhealthy. So now we have to take all of the traffic that was going to our on-prem environment, shift that back to the cloud, except that cloud is busy tearing down unhealthy nodes and spinning up new nodes. So then you just have a thundering herd, unhealthy, unhealthy, unhealthy, unhealthy, so on and so forth. Again, not great for anybody. So when teams attempt to solve these challenges and bridge these hybrid environments, which are called rudimentary or typical traffic management techniques, the architecture inevitably fractures against and across a variety of failure modes. We're going to focus on three particular failure modes today.

[5:26] First one is under or over -utilization because of blind round -robin traffic steering. That is a mouthful. Uh, round-robin is the... simplest the steering algorithm that you're going to find out there let's take request one send it node one quest two send it node two so on and so forth uh it's still around because it's incredibly effective except it's incredibly effective in very specific circumstances those circumstances being you're operating in an environment where all of your different environments have homogenous amount of capacity we're literally just taking the load shifting it out as evenly as possible about all of our different centers. But this begins to break down in heterogeneous environments with differing amounts of capacity, in which case you're either going to under -provision and your lower capacity sites are going to become overloaded, shift traffic elsewhere, or you're going to over-provision and then you're just going to be wasting money because you've over-provisioned and you're doing blind round -robin.

[6:23] So then surely a potential solution here is that we want to maybe route by latency. Yeah, it's got to be the solution. Unfortunately, again, probably not. Latency-based steering can work great, or it's great in homogenous environments, can also work great in some multi-cloud environments, because the latency that you're going to find from the end user to any of the big public clouds is typically going to be somewhere around the same. But as soon as you introduce on-prem hardware into the equation, the math just completely changes. So you have your cloud -based application will attract all of the traffic because it's going to be responding the most. quickly unless your users are directly co-located which typically is not going to be the case and then you have two outcomes outcome one your on-prem is just never going to see any traffic whatsoever you're going to be wasting money because you have servers that are sitting idle or outcome two you have issues in the cloud you try to shift traffic onto the on -prem and then we have that same thundering curve problem that we talked about earlier the third failure mode is configuration sprawl so say you want to do something as simple as manage a canary environment ordinarily that's going to be as simple as configure a few routing rules you know query query string header configure those routing rules boom you've got a canary environment when you're doing hybrid environments you then have to take that configuration replicate it from one spot to the next spot still not great even though there's maybe different configurations but what happens when you scale that to 10 applications and

[7:54] then 50 applications 100 applications applications as we'll see here in a little bit uh the management simply becomes untenable yeah there's ways to automate it but they're not they're not good solutions so to prevent these failures we have to move past and blunt routing rules and adopt a more intelligent capacity aware traffic management strategy uh a intelligent traffic management strategy should be able to accomplish at least these things probably more so capacity -aware distribution instead of doing something like proximity steering, blind round robin. You need to be able to direct your traffic on something more closely resembling the actual capacity of your backends. You need to be able to have programmable and easily manageable edge rules to take care of those edge cases, the canary use cases, things like that.

[8:42] Importantly, you need to be easily manageable. And then finally, you need uninterrupted resilience. We mentioned earlier that active-active is becoming the norm for both performance and cost reasons. An intelligent traffic... management platform needs to be able to failover seamlessly in near real time and take traffic that was destined for one location and shift it in a capacity aware manner to other locations now up until now this may have sounded all boringly theoretical i promise you it's not this is the exact production architecture that uber has deployed to scale on their cloudflare platform from zero request as of 2023 up to over a million requests per second today so i will invite oscar up on the stage as he's making his way up here we'll take a quick brief look at the time frame of uber's on ramping welcome oscar starts in 2023 we've got onboarding fast forward six months we are live in production six months later we're doing active active with cloudflare feature parity is at 99 and 30 of traffic's on cloudflare fast forward a little bit before today we're at 50 of core trips 100 of critical web app That's 100% of employee traffic.

[9:51] So with that, I'll hand it to Oscar to talk through the problems they encountered in this journey and how they solved them.

[10:02] Yeah, so my name is Oscar Marino Garza. I'm a software engineer on the internet traffic team, which, you know, you can probably guess from the name we handle the internet traffic coming into Uber. Just going to talk about some of the problems we've run into as we scale the systems. I think, like, you know, organizations are going to run into these problems sooner or later as you scale your systems. I also want to call out, like, these particular solutions make a ton of sense for Uber, but they might not be the best fit for your organization. So, you know, your mileage may vary. So, yeah, these are not silver bullets. Okay, yeah. So, big picture, right? H-2023. Uber started. with a single cloud provider, which was the FastPath.

[10:49] And then we had on -prem data centers that we could use as a backup. Fast forward to 2026, we now have ActiveActive with both GCP and Cloudflare as the FastPaths. But also, we retained the data center on -prem capacity, but we honestly don't use it that much. Now, this doesn't mean like, oh, it took us like three years to... onboarding to Cloudflare. No, it actually took us like around six months to serve like a decent amount of traffic. But we are continuing to work with Cloudflare on multiple different things. You know, HTTP3, the standardization is one thing that comes to mind. So there's like an ongoing effort going on. Yeah, and then just to clarify, like that MVP, six months, rider traffic.

[11:37] So if you ever requested an Uber, Uber Eats. That sort of stuff. Yeah, so basically, at the core, we have DNS that handles the kind of like, we have like a weighted DNS setup for ActiveActive, which we will send you to Cloudflare or GCP in this case. But for this, we're going to like focus on the Cloudflare configuration, which is pretty straightforward. We basically have a single zone for each. top -level domain. So, one for Uber .com, Uber Eats, so on and so forth. Right now, we have around like 120 to 115, I want to say. They keep growing. Yeah, but in general, for each particular website we have, we actually have around 6 ,000 configurations.

[12:26] So, overall, across all of those aggregated, 6 ,000 different website configurations. And what do I mean by configuration? It's like term right so basically like nginx and our proxy configurations later down the stream so where do i route to uh on the uber service match what else what is like the authentication level for this request and then there's also like things like okay what kind of parameters does this map against our ddos efforts so a lot of those it's a pretty big configuration there's 6 000 of them um it's It's a lot to manage. So obviously we don't want to create 6,000 Cloudflare configurations for this.

[13:12] That's why we only create the top zones and then manage the more like Uber specific logic inside our Amboy proxy and NGINX services. I also want to say like, in general we are currently handling right now around like 2.2 million requests per second. So half of that traffic goes to Cloudflare, but also during important dates such as Halloween, 4th of July, that traffic can add doubles, right? So we have to also keep that in mind when we are designing our systems.

[13:50] Now, this doesn't mean like, okay, you mentioned there's a lot of over-specific logic later down the stack. This does not mean like Cloudflare is just like a simple proxy. We just send all of... the traffic. No, no, it handles like a lot of really important configurations and like most notably like TLS, MTLS for some users, DDoS, volumetric protection, but also the first hope in our load balancing scheme. Right. So I'm going to talk a little bit about the Uber kind of like architecture. At its core, we have like a regional topology and we have two. regions, DCA and Phoenix, and they are named after the closest data center. So there's one in Washington, one in, you know, closer to Arizona. And then inside those regions, we have zones.

[14:42] And, you know, for the example, for Phoenix, we have like Phoenix 7, 8, and 9. These are kind of like what we look like a couple of months ago, where all of those zones are on -prem. So they look pretty much the same. Even though if you've read like blogs about Uber, our compute kind of like closer is heterogeneous. We are kind of like a special team. We get like special preferential treatment. And all of our hardware looks the same to help us make sure that we're able to route traffic safely to the backend services. So for this particular configuration, everything looks the same.

[15:22] Yes. Yeah, I also want to say like.

[15:28] The way that this is designed as it is, is because whenever there is like an issue on a region or a particular zone, we are able to quickly just flip a switch and enable or disable one of the pools or the backends, the endpoints, and it just takes like a couple of seconds, which is amazing. I don't know what kind of Magic Cloudflare is running there, but it's so good to know that you can drain in like one or two seconds.

[15:57] Now, here's kind of like the first problem, is what happens when your assumptions around homogeneous capacity but also latency are broken, right? So there's this big push to migrate to cloud and we set up a cloud zone. Everything's perfect, everything works, but the moment we start sending traffic to it, we realize, okay, there's two problems here. One is the new Cloudflare back zones have like a much better latency, right? Usually cloud providers are much better latency than if you go and build your own data center, right? They just have those intercontinental cables in the sea, right?

[16:43] But also the other problem is not only the latency is better, but the throughput for this new... servers is actually a lot better too, right? So now you have like those two problems that you have to figure out, right?

[17:00] So, yeah. I mean, if you just go and use one of like the default.balancing algorithms, like that might work out like perfectly okay, right? Specifically if you're like just focusing on latency because latency will encode things like capacity by default. But we care not only about latency, but also about the utilization, right? We want to make sure that if we are paying for a specific server, we actually get the full use out of it so we can pass the savings to the customer.

[17:34] So how do we become explicit and encode this sort of capacity slash latency on the backends? Yeah, so luckily for us, there is a very well -known algorithm that Cloudflare already has on the traffic stack. It's called weighted round robbing, and it's super simple. You just set a weight for each backend inside your pool, and then you can play around with the capacity and latency and a bunch of different factors. And then for our Phoenix 50, so on, which these are mostly real numbers, we just kind of put a... 2x factor on it. So that gets like 50 % of the internet traffic, and then the other legacy on -prem servers get 25 % and 25 % each.

[18:20] So now everything is like perfectly balanced, right?

[18:29] Yeah, I know like with it's round robin, it's probably not like super groundbreaking, but honestly, I kind of love it. I feel like you have to be like a genius to come up with this with the algorithm in itself. actually you can like encode so many different things and look into that particular number um so for us we care about the latency there's like some piece of code somewhere running on the uber stack that updates this on the flies based on capacity uh throughput and also like the latency um yeah i want to kind of like have a little pause here and give a bit more context about some of the uber architecture before we go into the second problem and basically the main thing you need to know is the mobile application actually uses like different hostnames, like DNS hostnames in order to run different sort of experiments, right?

[19:26] We mentioned like HTTP3, there's a specific hostname we are reserving to do some testing on HTTP3 We have this service called Dispatch Center which, you know, at its core I mean, it's a very complicated service core, it's a key value data store, and you can map a request to a specific host name and then map that particular host name to an experimental group, right? And then an experimental group has some routing, some Uber -specific routing characteristics that will push you to a specific instance on our Kubernetes cluster. So using this dispatch center service is how we've implemented Canary Routing for Uber. So, yeah, actually, I guess, like, surprise announcement also for Uber employees.

[20:13] We've been running this for a couple of months now. We've never made it kind of public. But if you're an Uber employee, you are already, like, being to Canary right now. If you open your mobile application and just look at the network logs, you will see, like, CN Canary, CN Canary. But, yeah, just a little bit more context. CN.uber.com is our main API. CN Canary is like our new Canary host name. So, okay, here's a bit more context. We have this system that kind of rolls out in a sequential manner to two different zones. And inside our stack, we reserve DCA 20, the zone specifically for Canary.

[21:01] So this is like a very small zone. supposed to serve at max 2% of the global traffic.

[21:09] So here's the problem. How do you make different routing decisions

[21:15] for different subdomains, right? So we have seen .uber.com, which is our main configuration. We are perfectly happy with it, right? But now we want to say, okay, for seeing cannergy.uber.com, we want to change the routing. Now we want to include the SA20 and maybe ISO. DCA20 so that all of the canary traffic is like isolated into that particular zone which all of the over services for canary are running in and it gets like scrutinized for like metrics and logs and observability um so yeah there's kind of like the naive solution and I mean I think I think this kind of works if if your scale is not like super big or you don't care to manage 6 ,000 zones and duplicating that but you can just say okay let's just make create a cloud first zone for cncana readover .com right we talked about earlier how we don't do that and that is because then our configuration will grow like exponentially and I mean we just don't manage that right like that's that's a nightmare to manage so if only there's like a way in which you know you can define an exception for a configuration without actually taking extra complexity in either one exploring your configuration or the other kind of thing that we thought about doing is, okay, we have this system that pushes configuration to Cloudflare.

[22:42] What if we add like a little if branch in there? If you are seeing canary.uber.com, then just create that particular zone and then do something else for the rest. Yeah, none of those. are particularly interesting for us. Like, they're not very something we want to manage at additional if branching or manage, like, a huge configuration set. So, yeah, turns out there is already a thing that we're leveraging, and I want to give a shout-out to Chris Martinelli because we can engage with him.

[23:23] trying to come to a solution to this problem. And, you know, the suggestion was, okay, just use the load balancer custom rules. And, I mean, yeah, I mean, I think this makes sense, right? If you're not familiar with the custom rules, they basically allow you to map a particular request to an action, right? And in the case of cncannery.rober.com, like, it might be unsurprising that we map that particular host name, and then we set up an override pull action, and we only have... DCA20 as a primary pool. We have the rest of them for backup in case DCA20 has an issue. But in normal operation, everything is isolated to that particular

[24:04] There's a couple of things that I really like about this approach. One is you don't have to create 6,000 zones, right? 6,000 clausular zones. That would be madness. And then the other one is even if you were to create the 6,000 zones, you have to think about okay, am I going to create, like, duplicate load balancers for each zone? Am I going to create, like, duplicate pools? Are the pools going to share health checks? Are they going to duplicate the health checks? Yeah, health checks alone are, like, a significant amount of traffic for us. So, actually, this solution just allows us to say, okay, we just have, like, one extra pool that we can share across all of the zones, just one extra health check that we are able to kind of, like, ramp up and be a little bit... more quick on that health check and failover faster.

[24:50] And then the other thing that I really like is that actually like if you look at the configuration in itself, it's the same across every zone, right? Yeah, I mean sure you have like that kind of like branch on the rules itself, but if you look at the configuration and what you need to understand as a human, everything is the same for all of the zones. So yeah, that's what we end up using. And I think that's it.

[25:15] Throw it back to you.

[25:20] Thank you.

[25:23] Oscar. So everything we heard Oscar talk about, think about the weighted round robin specifically. I want to give a quick preview of something that's going to be coming very soon to look out for their load balancing. It's called dynamic load shedding. You may hear this referred to in other contexts as feedback-based load balancing. With something like weighted round robin, it's still on you to intuit what the... of a particular area, particular application is. With feedback-based load balancing will allow you to return a load metric for a particular origin. This one's a 10%, 20%, 30%. That can be CPU, that can be an arbitrary metric, whatever it is that you decide. Do our active health checks. Then within Cloudflare, you set a target. And then once we begin to meet and exceed that target, we will actively shed traffic away from that endpoint and pool to prevent it from becoming overloaded in the first place.

[26:11] So rather than having to guess that, yeah, 30%, 50%, whatever, works. We're actually low-bounding based on the capacity that you're returning to us. Then a little bit later down the line, dynamic origin registration. We're exploring ways that we can integrate with the dynamic scaling nature of a lot of workloads today, so that rather than having to run API calls, we can just autonomously know that you're scaling up and down, add those new endpoints to pools, and then everyone's happy because you don't have to manage scripts. and things like that.

## Related sessions

- [Zero trust in railway OT: What worked, what broke](https://www.cloudflare.com/connect/2026/session/zero-trust-in-railway-ot-what-worked-what-broke)
- [How to measure real-world network quality for end users](https://www.cloudflare.com/connect/2026/session/how-to-measure-real-world-network-quality-for-end-users)
- [Co-engineering the future: How Uber & Cloudflare engineer a global platform](https://www.cloudflare.com/connect/2026/session/co-engineering-the-future-how-uber-and-cloudflare-engineer-a-global-platform)

## More from Connect

- [All sessions](https://www.cloudflare.com/connect/)
- [Get notified for Connect 2027](https://www.cloudflare.com/connect#2027)


